AI (artificial intelligence) is a powerful tool and system whose inner workings are beyond the realm of our current understanding…
It might be able to analyse massive amounts of data, finding correlations and connections that humans can’t, but it can’t explain the steps it took to get to the final answer. This is the essence of the technical and philosophical conundrum called the “black box”: we can see what comes out and what goes in, but what happens within is a mystery – and it cuts to the heart of the relationship between humans and the machines they’ve created.
“Black box” comes from systems theory, which describes a system or device analysed in terms of its outputs and inputs only, with no information of how it works internally. When applied to AI, specifically modern DL systems, the metaphor is alarmingly apt. These systems are fed data and produce results, but the transformative processes that occur in the middle are largely opaque.
This article examines AI’s mysterious black box problem, its challenges, and the reason we’re still using them.
How Do Black Box Systems Work?
While we can see the outputs and inputs of the black box AI system, its inner workings are a mystery. Consider a model that assesses the resumes of job candidates, where users are able to view the resumes fed into the model, the inputs, and their assessments it returns, which are the outputs. However, we don’t know how exactly it arrives at those conclusions, especially which factors it takes into consideration and how it evaluates them.
A major chunk of today’s most advanced ML (machine learning) models, including Meta’s Llama and OpenAI’s ChatGPT, are AI black boxes. However, because their workings aren’t exactly transparent, it’s challenging to trust the outputs sometimes, despite the complex systems delivering the most impressive results. If users don’t exactly know what’s going on beneath the hood, they won’t be able to validate a model’s outputs easily. Moreover, black box models are opaque, hiding issues such as privacy violations, biases, and cybersecurity vulnerabilities.
So, why are their black box systems existing in the first place? The reason is two-fold: they became by-products of their training or their developers making them on purpose. Some AI programmers and developers use it to protect intellectual property by obscuring the model’s inner workings before releasing it to the public. But, many of them, including GenAI (generative AI) tools, are “organic black boxes,” where the DL (deep learning) structures and systems powering the models are complex to the extent that even their developers and creators themselves don’t exactly understand what goes on within them.
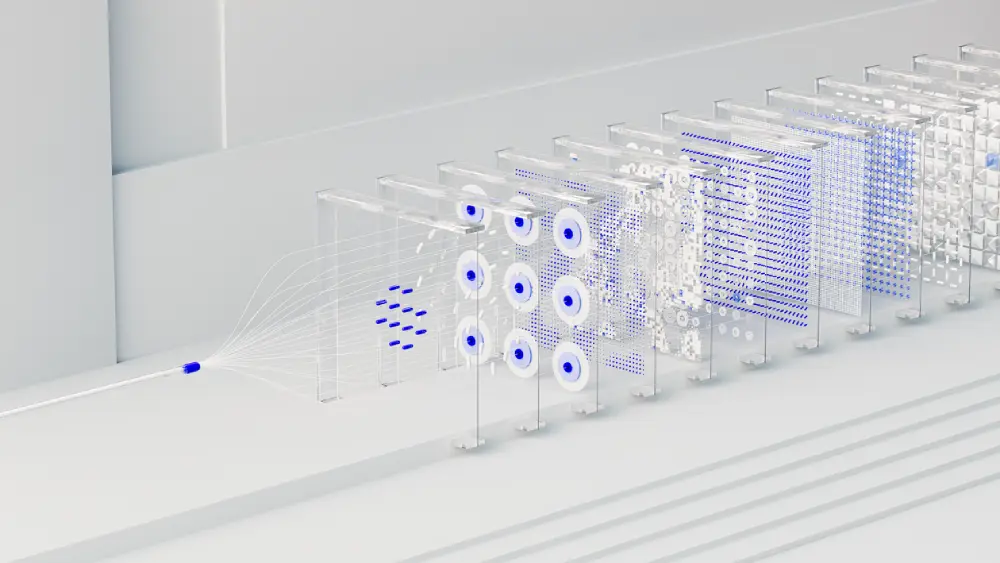
Since DL algorithms use complex neural networks with multiple neurons, are fundamentally opaque. Even AI developers, who understand how data travels through each of the network’s layer broadly, are unaware of all the particulars. For instance, chances are they don’t know how the system finds and puts vector embeddings together exactly while responding to prompts or what it means when a specific set of neurons activate.
In fact, open-source AI models sharing their fundamental code are black boxes in the end as well, as users still can’t fathom what goes on inside the models’ layers when they’re active.
Black Boxes: The Problem
Myths are a crucial in the AI realm, and black boxes are woven into the stories they tell. The most cutting-edge ML/AI models today might be tremendously powerful, but they aren’t interpretable. The fact that we haven’t been able to fully understand the inherent intricacies of the model have raised ethical, legal, and practical questions. If these black boxes are being employed to make high-stakes decisions in judiciary, healthcare, insurance, lending, or other areas of finance, we have to decide whether or not we’re comfortable with not knowing why a certain decision was made specifically.
Specifically, black box AI poses challenges such as reduced trust in the outputs of the models, challenges in adjusting the models’ operations, security issues (they’re susceptible to data poisoning and prompt injection attacks), a boatload of ethical concerns, especially their susceptibility to bias, and regulatory non-compliance.
So, while black box learning models have practical reasons for their use, the fact that they aren’t transparent could prove to be an impediment to getting to their full value.
What now?
As Pedro Domingos says it so eloquently in his 2015 important work “The Master Algorithm,” ML is akin to farming where the ML expert is the farmer planting the seeds (the data and algorithm), harvesting the crop (the classifier), and selling it to customers – all without necessarily understanding the biological mechanisms involved in the growth.
Throughout history, humans have created tools that extend beyond our complete understanding, whether it’s financial markets or artistic expression. The black box phenomenon isn’t just a technical challenge but forces humans to confront the limitations of our grasp of the concept in the face of this complexity.
As we navigate this territory between mystery and knowledge, the most possibly fruitful tactic to understanding the black box’s nature lies in embracing both the limitations and power of these technologies, rather than demanding complete transparency.
In case you missed:
- AI Runtime Security: A Comprehensive Look
- Are AI Tokens the New Digital Currency?
- Governing AI Agents In The Agentic Era: Are We Truly Ready?
- All About India’s Indigenous AI LLM Models – Can They Help Tackle Bias?
- All About Data Poisoning Cyberattacks
- A Complete Guide To Open-Source Software
- Is GPU-As-A-Service The New Cloud Gold Rush?
- The Intelligence Swarm: How Bees Are Helping AI Become Smarter
- The Indian Indigenous AI Model Map
- Agentic AI Is Now A Fund Manager, Believe It Or Not